Claude Now Leads 26% of Its Own R&D. Steal the Yardstick, Not the Number.
Anthropic says Claude now leads 26% of its own R&D, up from under 1% in February. The AL0-AL5 scale behind that number is the part worth taking for your own team.
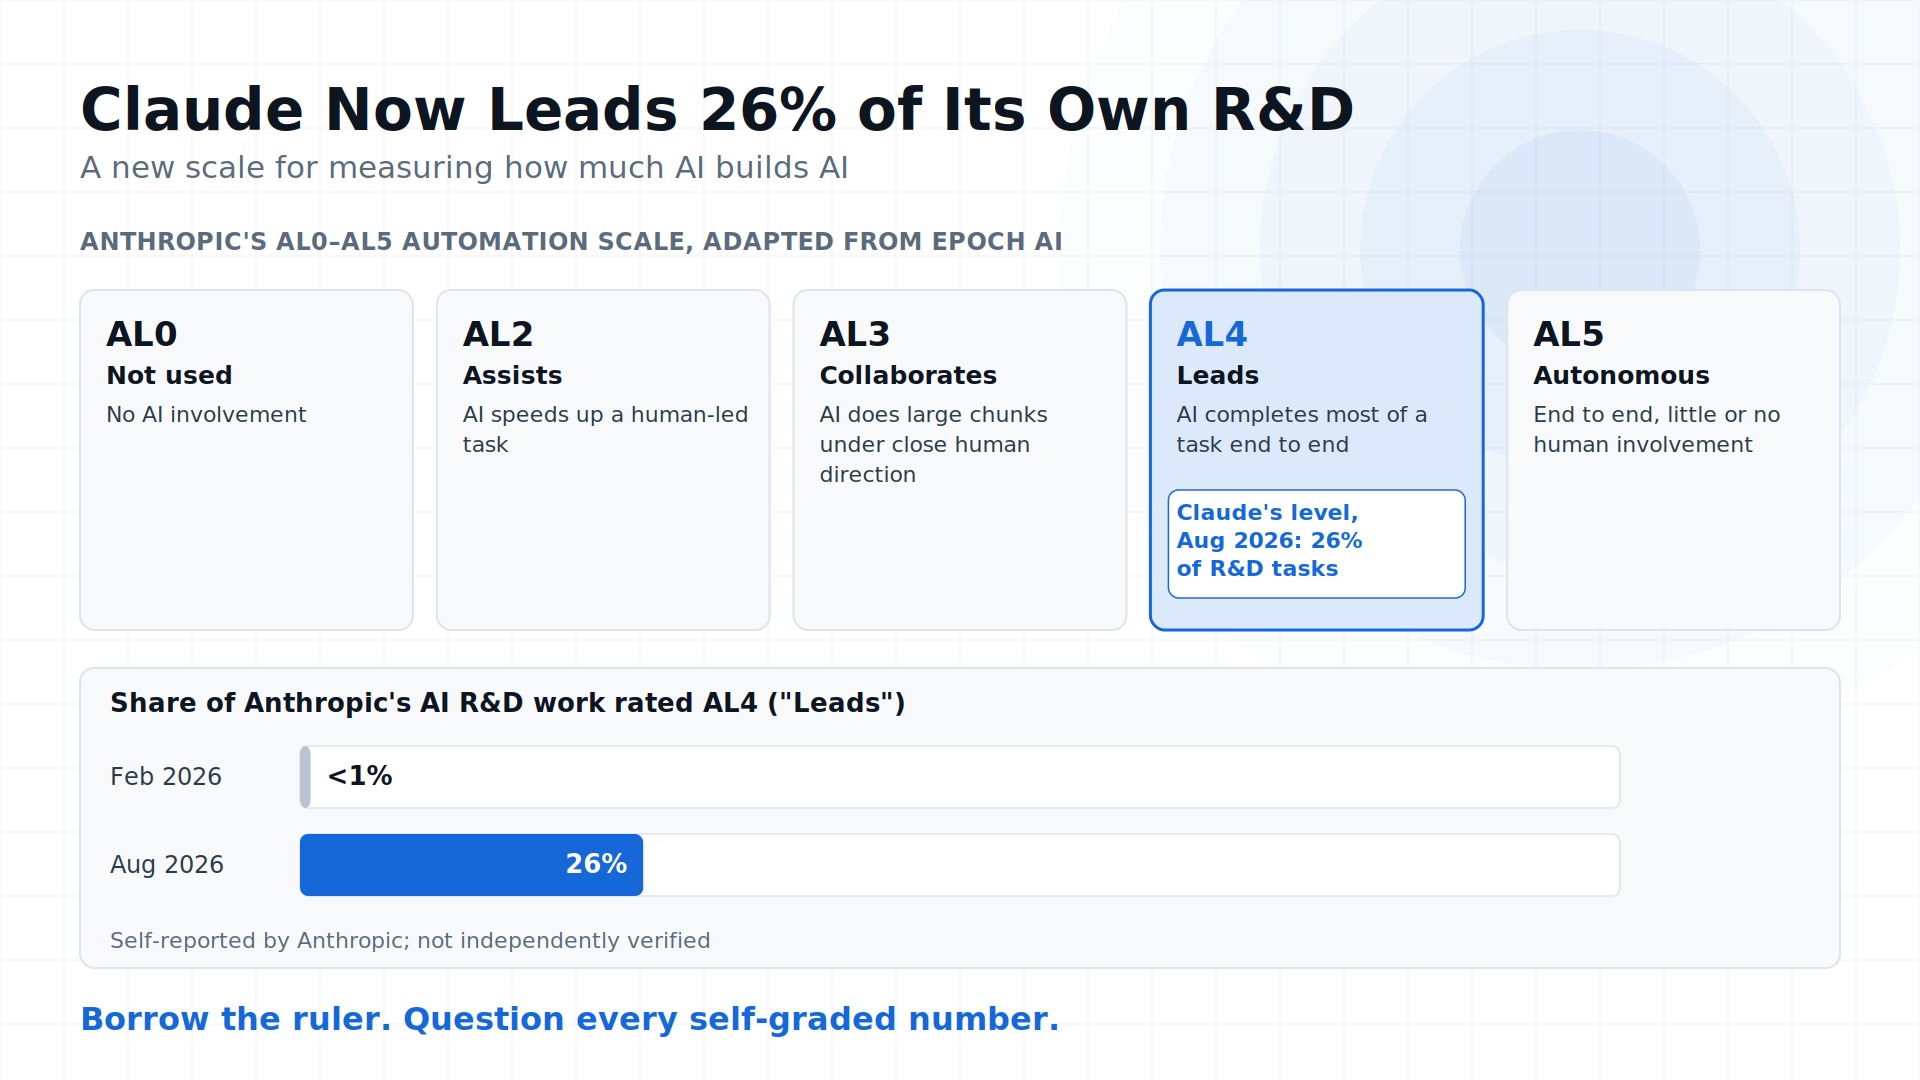
Anthropic says Claude now "leads" 26% of the company's AI research and development work, up from under 1% in February, a 25-point jump in six months. The number matters less than the scale Anthropic built to produce it, a six-level system for describing how much of its own next model Claude is building.
Anthropic's writeup uses six automation levels, adapted from a similar scale Epoch AI proposed for classifying AI R&D tasks.
| Level | Name | What it means |
|---|---|---|
| AL0 | Not used | No AI involvement |
| AL2 | Assists | AI speeds up or improves a human-led task |
| AL3 | Collaborates | AI does large chunks of the work under close human direction |
| AL4 | Leads | AI completes most of the task end to end from a high-level prompt, human still supervising |
| AL5 | Autonomous | End to end with little or no human involvement |
The 26% figure is AL4. Anthropic is explicit that none of the measured work hit AL5 yet.
Claude produced most of the ratings that generated that 26% figure. Anthropic checked Claude's classifications against human graders and got 59% exact agreement, against a 35% baseline for two humans rating the same work against each other. That's a real result. Claude was more consistent than a second human grader would have been.
It doesn't change who picked the tasks, who held the records, or who built the rubric. Anthropic did all three. Claude did the grading.
The rest of the post backs that up with operational detail. About 30,000 agents ran research and engineering work simultaneously on Anthropic's internal platform in August. Online monitors covered every one of the resulting decisions and blocked roughly 1 in 47,000 of them, out of more than a billion. Compute set aside for safety work ran 6% of total R&D spend in mid-July, rising to 12% for the AI-driven slice specifically, numbers Anthropic itself calls conservative. Third-party evaluators aren't in place yet. The post says they're coming.
This is a detailed status report, published by the people whose job is to make you believe the status is handled.
The AL0-AL5 scale is a better tool than whatever your engineering org currently uses to talk about AI on the team. "AI helped a lot this sprint" gives you nothing to track quarter over quarter. Pull last quarter's closed PRs and tag each one AL0 through AL4: fully human, AI-assisted, AI-drafted-then-heavily-edited, or AI-led-end-to-end-with-review. That gives you an actual distribution to show your board before anyone claims how much of the roadmap an agent is carrying.
Don't treat Anthropic's 26% as evidence of anything beyond Anthropic's own workload. It's self-reported, scored by the tool being scored, drawn from tasks the vendor selected, and unverified by anyone outside the building, a gap Anthropic names in its own post. A lab facing public pressure to justify racing ahead, while its own CEO is on record calling for an industry-wide slowdown, has every reason to publish a number that reads as impressive and under control at the same time. Both can be true. Neither is checked yet.
Run the AL0-AL5 audit on your own last quarter before you repeat anyone's automation percentage in a planning doc, including the one you're about to pull from this post.
Found this helpful? Share it with others!